
Databricks RAG Master Course: Build Production AI Pipelines
Published 8/2026
MP4 | Video: h264, 1920x1080 | Audio: AAC, 44.1 KHz, 2 Ch
Genre: eLearning | Language: English (US) | Duration: 2 h | Size: 605 MB
This course contains the use of artificial intelligence.
Stop stitching together disconnected AI tools. Build RAG the way it's meant to work — inside Databricks.
If your company runs on Databricks and you've been asked to build an AI search or chatbot feature over your own data, this course takes you from raw documents in Unity Catalog to a fully deployed, governed RAG pipeline — step by step, with real, runnable notebooks.
This course is for you if:
You already work in Databricks (Spark, Delta Lake, notebooks) and need to add an AI/RAG feature
You've tried generic RAG tutorials that ignore governance and don't fit your company's platform
You want to understand Mosaic AI Vector Search and Agent Bricks without guesswork
You need a production-ready pipeline, not just a notebook demo
You want a real, deployable project for your portfolio or internal team
What you will learn:
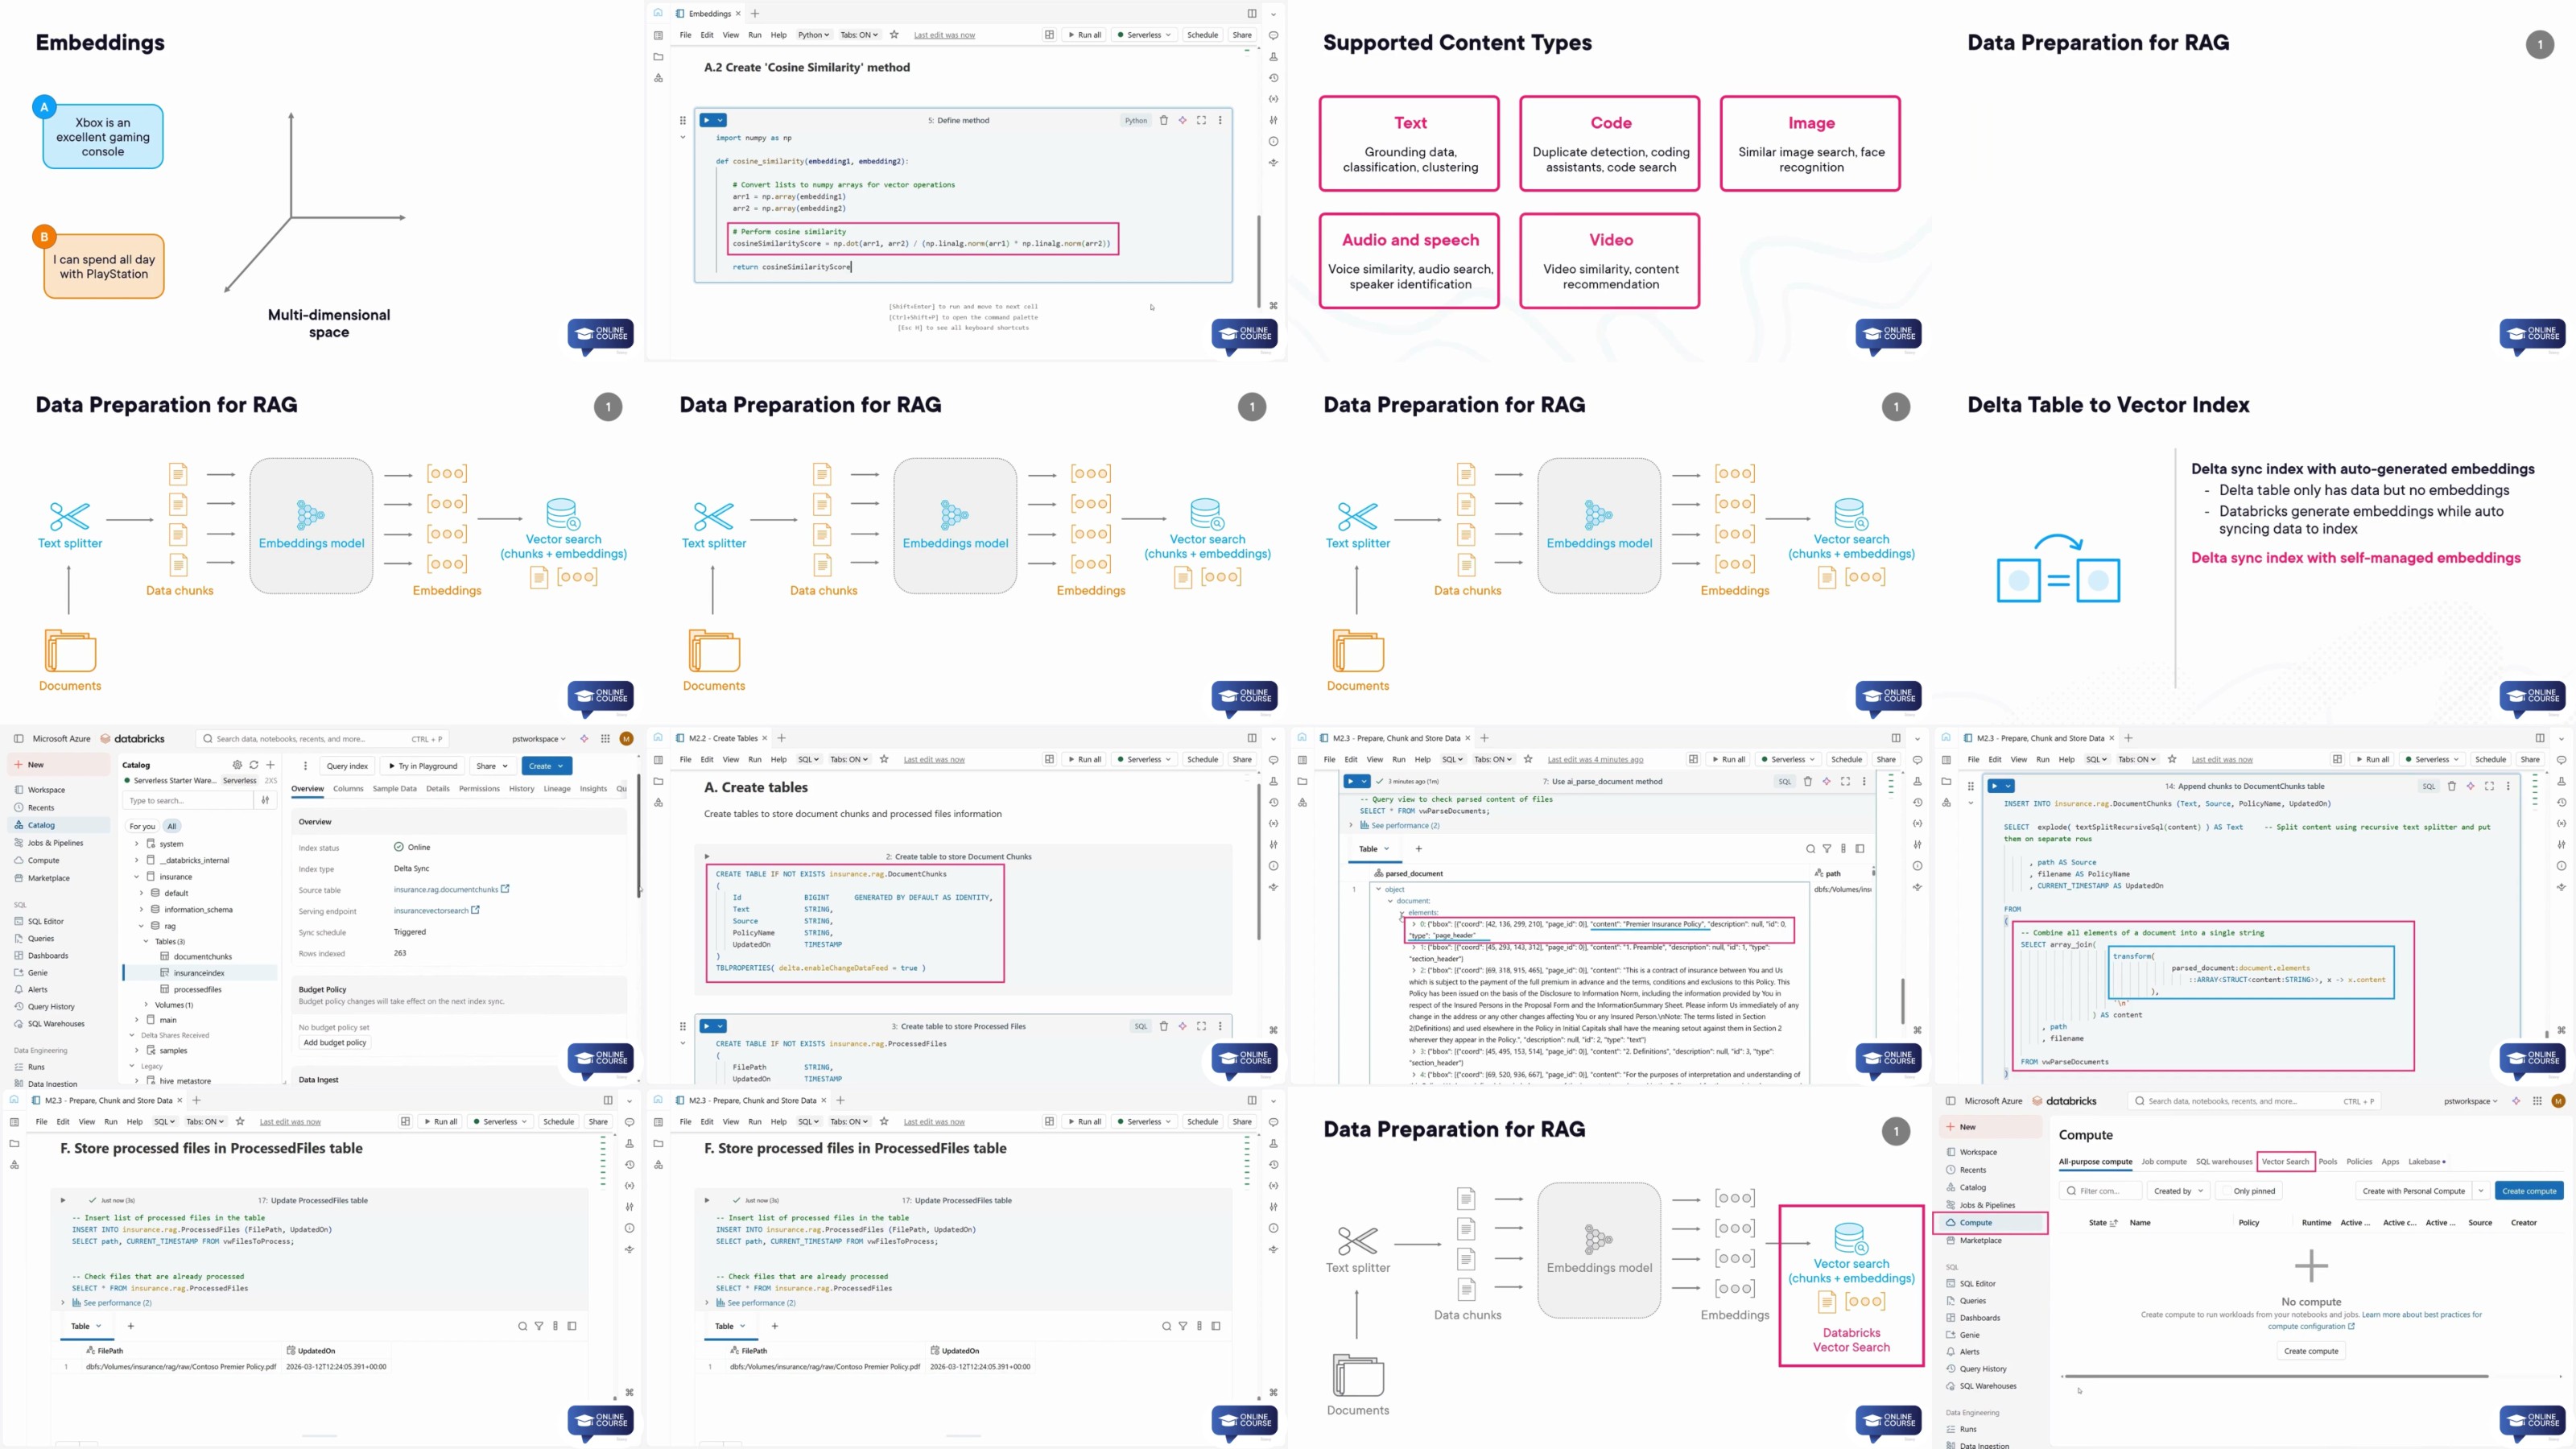
Understand the full RAG architecture and how it maps to the Databricks AI stack
Choose the right chunking strategy for different document types
Generate embeddings and build a Mosaic AI Vector Search index from Delta tables
Build a complete retrieval-to-response RAG query pipeline
Use Agent Bricks to configure a managed, multi-step retrieval agent
Build a golden evaluation set and score retrieval and answer quality
Deploy a RAG pipeline as a governed Model Serving endpoint
Set Unity Catalog permissions to control who can access your AI agent
Keep your vector index automatically in sync with changing source data
Monitor cost, latency, and usage of a deployed RAG agent in production
Requirements:
A Databricks workspace with Unity Catalog and Mosaic AI features enabled
Basic Python and SQL knowledge
Basic familiarity with Databricks notebooks (Spark experience helpful but not required)
Final project:
You will build and deploy a complete, governed RAG pipeline — from document ingestion and chunking through vector indexing, evaluation, and a live Model Serving endpoint — that you can demo directly to your team, a client, or a future employer.
More Info

RapidGator
DDownload
NitroFlare
We need your support!
Make a donation to help us stay online

Bitcoin (BTC)
bc1q08g9d22cxkawsjlf8etuek2pc9n2a3hs4cdrld

Bitcoin Cash (BCH)
qqvwexzhvgauxq2apgc4j0ewvcak6hh6lsnzmvtkem

Ethereum (ETH)
0xb55513D2c91A6e3c497621644ec99e206CDaf239

Litecoin (LTC)
ltc1qt6g2trfv9tjs4qj68sqc4uf0ukvc9jpnsyt59u

USDT (ERC20)
0xb55513D2c91A6e3c497621644ec99e206CDaf239

USDT (TRC20)
TYdPNrz7v1P9riWBWZ317oBgJueheGjATm